01
Specialized LLMs for closed environments
Open models from 1B to the 750B scale, from data and evaluation design to on-prem / closed-network operation.
AI services
Post-training know-how from 750B-scale models, for LLMs that run in your closed environment — and assistive AI built by the people who use it.
01
Open models from 1B to the 750B scale, from data and evaluation design to on-prem / closed-network operation.
02
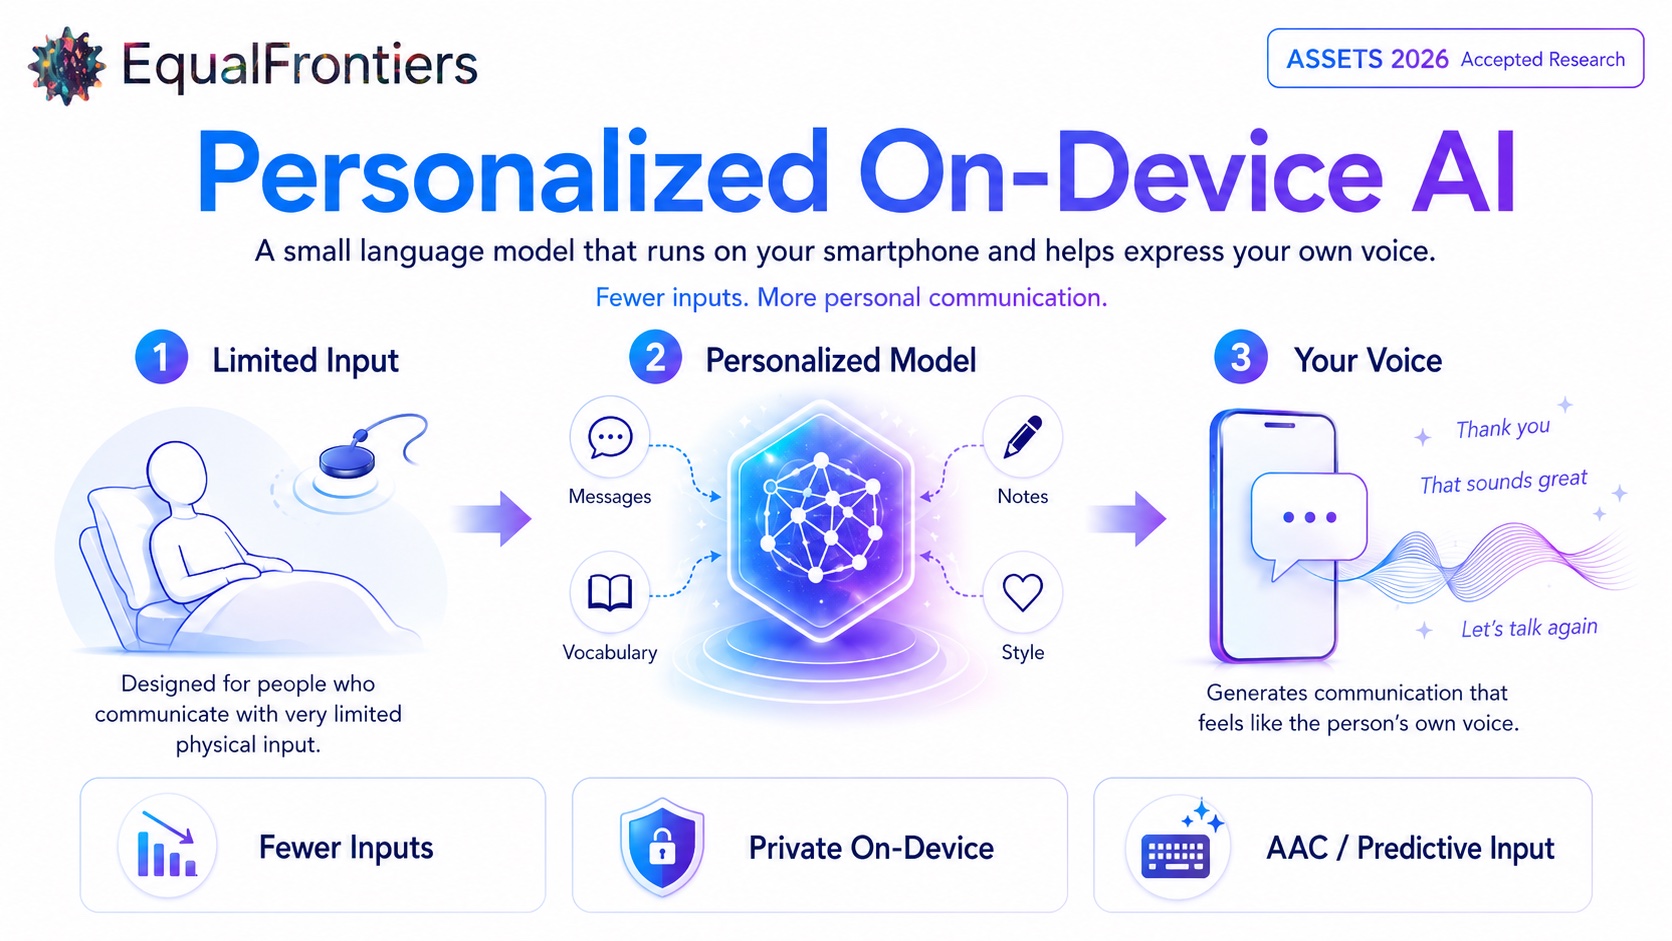
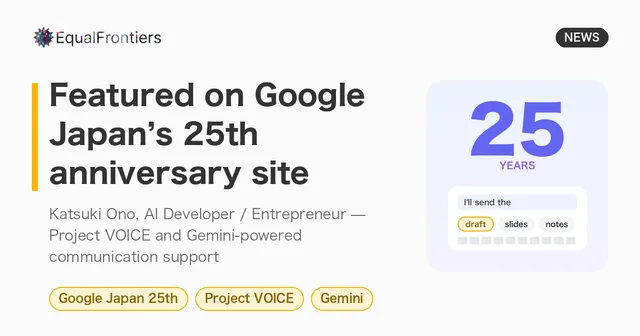
Personalized on-device AI, AAC, input assistance. Google Project VOICE collaboration; ASSETS 2026 paper.
Other services: Business AI (RAG, chatbots) / Inclusive LLM Translation
01
We train open LLMs to fit your business, your data and your operating environment, so you can use LLMs even for work whose data cannot go to the cloud.
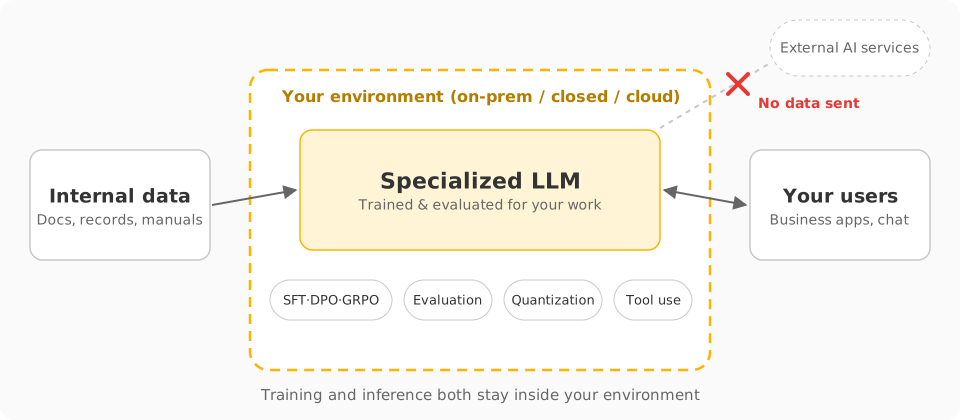
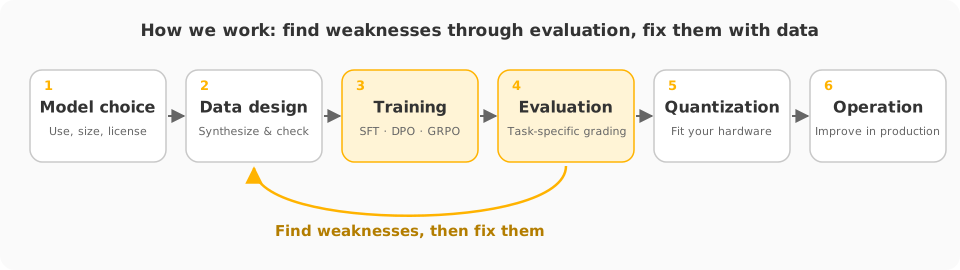
Specialize open models with SFT, DPO, GRPO and more — up to tool use, training models that call search, calculation, internal systems and APIs (agentic workflows).
Pipelines that generate training data from your documents and have another model check facts and quality, so training can start with little data.
Task-specific evaluation sets and automatic grading, driving a cycle that finds and fixes weaknesses.
From training under limited compute (FSDP, distributed training, parameter freezing) to quantization, inference optimization and setups where data never leaves your environment.
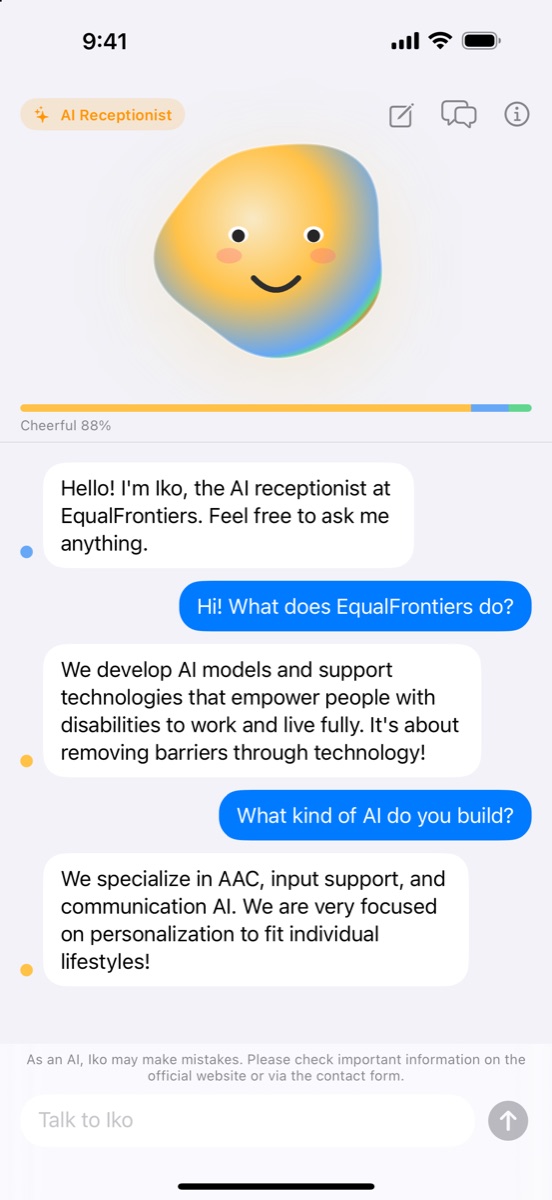
Tech demo
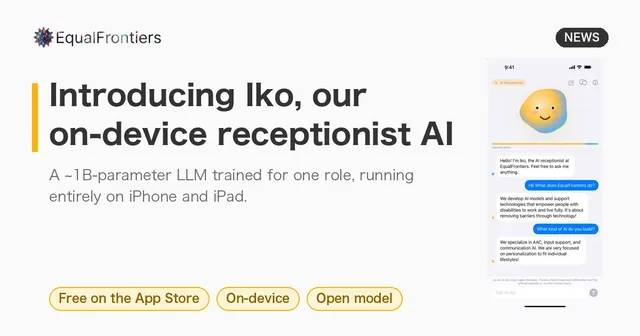
Iko takes a ~1B-parameter model, trains it into a single role through data synthesis, SFT, DPO, long-conversation training and quantization, and runs it entirely on iPhone and iPad. The same methods scale to larger models.
02
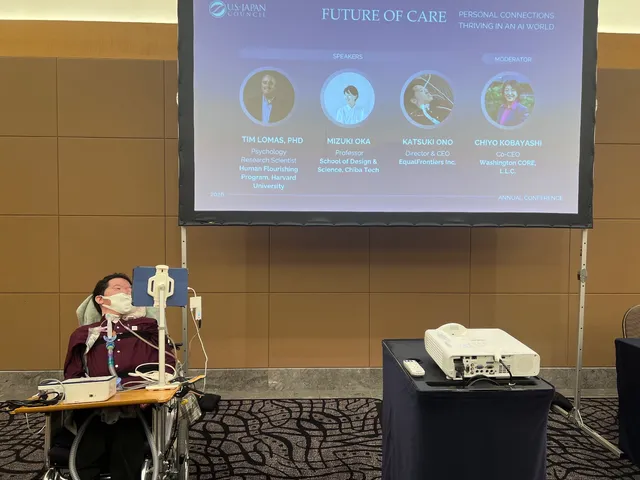
Our CEO, Katsuki Ono, cannot type, speak or move his limbs; he operates a tablet through one switch mounted beside his head. He developed eleven generations of a personalized language model that predicts his own words.
We focus on preserving the user's voice, transferring intent with minimal input, and being usable in real life, work and care settings.
Challenge: build a large language model specialized for medicine.
Role: sub-team leader of a 10-person post-training team, building the SFT and DPO training pipelines.
Approach: combined parameter freezing with fully sharded data parallelism (FSDP) to train models up to 744B parameters (GLM-5) under limited compute.
Challenge: let people who cannot easily speak or move convey words that are truly their own, with minimal input.
Role: fine-tuned Gemini on about 50,000 of his own messages, built an auxiliary model to synthesize training data, and iterated through eleven versions.
Result: a model whose output his family recognizes as authentically his voice; the project received an iF Design Award Gold Award.
* Client engagements are confidential; we share what we can in individual consultations.
RAG, summarization, translation, classification, internal document search, communication-support AI — realistic deployments shaped by your objective, budget and environment. OSS models are supported for offline / on-prem deployment.

AI translation combined with review by disabled staff — short turnaround, high quality and reasonable pricing in a single workflow.
Our team continues to publish research on LLM training efficiency, model analysis and assistive AI to the extent confidentiality permits.
Note: specific client engagements, model details and ongoing peer-reviewed research are not disclosed due to confidentiality and double-blind review requirements. We are happy to discuss relevant scope and capabilities under NDA.

For AI development, LLM R&D, or assistive AI inquiries, please use the form below. Briefly include your project area, timeline, and deployment environment if possible.
This site uses cookies for analytics. Privacy Policy